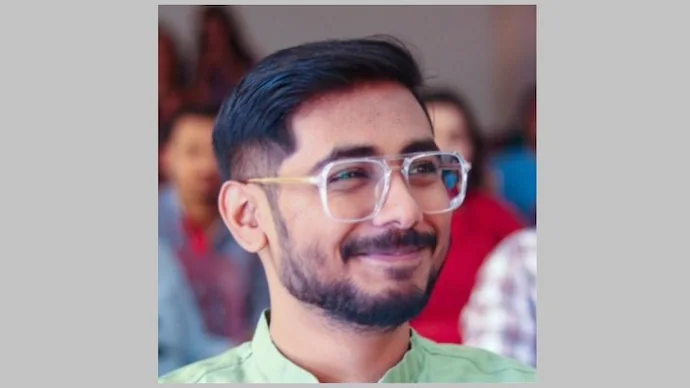
Building Artificial Intelligence models often requires substantial computing resources, large datasets and significant financial investment. Jitesh Prasad, the founder of Udgam Labs, is exploring a different approach: developing compact AI models with limited resources and publishing the results for others to examine.
In October 2026, Udgam Labs released a series of models covering speech recognition, reasoning, mathematics, image generation and conversational AI. The rapid sequence of releases drew attention to a broader question facing the AI industry: how much computing power and money are actually necessary to build useful models?
Prasad’s work is notable not simply because several models emerged within a short period, but because the projects include publicly available training details, code, model checkpoints and evaluation results. The approach allows other developers to inspect the work, assess its limitations and compare its performance against existing models.
Prasad studied physics at the University of North Bengal before completing an MBA at the Indian Institute of Management Lucknow. Through Udgam Labs, he has brought together an interest in technical experimentation and the practical constraints of building technology, focusing on what smaller AI systems can accomplish without the resources typically associated with major AI laboratories.
Who is Jitesh Prasad, the founder of Udgam Labs?
Jitesh Prasad’s academic background combines two disciplines that approach problems from different directions. Physics emphasises measurement, experimentation and the investigation of underlying principles, while business education introduces questions of cost, scale and execution.
That combination provides useful context for understanding his work at Udgam Labs. Rather than focusing exclusively on building increasingly large models, the laboratory’s recent projects examine whether carefully designed, compact systems can deliver useful results with substantially fewer parameters, less training data or lower development costs.
The central idea is not that computing resources are unimportant. Training and evaluating AI models still requires technical infrastructure, and the results depend on factors such as the quality of training data, model architecture, evaluation methods and the task being tested.
Instead, the work explores whether some AI capabilities can be developed more economically than conventional approaches might suggest. By publishing details of the experiments, Udgam Labs makes it possible for other researchers and developers to assess the evidence rather than rely solely on claims about model performance.
One particularly revealing aspect of the laboratory’s approach is its willingness to publish results that fall short of expectations. According to the supplied account, one of Udgam’s recent English models did not meet its stated performance target. The training material, evaluation and limitations were published alongside the result.
That transparency matters because a model’s value cannot be established simply by announcing its release. Independent scrutiny requires enough information to understand what was tested, how the results were obtained and where the system performed poorly.
Laghu: A compact chat model trained for $146
One of Udgam Labs’ most striking projects is Laghu, a conversational language model with 152 million parameters. According to the published figures described in the supplied material, its main training run cost $146, while the entire project cost approximately $194.
The main training run took 13 hours using eight NVIDIA A100 GPUs. The project also made its figures, code, model checkpoints and evaluation results publicly available.
The distinction between the training-run cost and the total project cost is important. The $146 figure refers to the main run, whereas the approximately $194 figure represents the broader project cost reported in the source. Treating the two numbers as interchangeable would give an incomplete picture of the resources involved.
Laghu illustrates the type of experiment Udgam Labs is pursuing: building a relatively small model from scratch and documenting the process so that others can examine its development.
However, low training cost alone does not establish that a model can replace a much larger commercial system. Performance depends on the task, the quality of its responses, the evaluation benchmark and the requirements of the intended application.
The more useful question is whether a compact model can perform particular tasks well enough to justify its cost and resource requirements. A smaller system may be attractive for specialised applications even if it does not match larger models across a broad range of capabilities.
For developers working with limited budgets, transparent experiments such as Laghu can offer useful information about the practical trade-offs involved in training smaller language models.
Shruti: A 29.5 MB speech-to-text model
Udgam Labs also developed Shruti, a speech-to-text model with a reported size of just 29.5 MB. The model was tested on Hindi, Hinglish and English speech, addressing language settings relevant to users who communicate across Indian languages and English.
Its reported evaluation results show why compact AI models should be assessed by individual tasks and languages rather than by a single headline performance figure.
On the Hindi material used in the comparison, Shruti recorded fewer errors than Whisper large-v3, according to the supplied account. On English, however, Whisper large-v3 remained ahead.
This difference is significant because speech recognition performance can vary considerably across languages, accents, recording conditions and evaluation datasets. A result on one Hindi test set does not automatically establish that a model will outperform a larger alternative on every Hindi-speaking population or real-world recording.
Likewise, the English comparison shows that Shruti’s compact size does not translate into universal superiority. The larger model retained an advantage on the English material described in the source.
For practical use, a speech recognition system’s suitability depends on more than its file size. Developers may need to consider recognition accuracy, latency, hardware requirements, language coverage and how well the model handles noisy audio or different speaking styles.
Even with those qualifications, Shruti demonstrates why lightweight speech models are worth investigating. A model with a small storage footprint could be useful in applications where downloading or deploying a larger system is inconvenient, provided its performance meets the needs of the intended task.
Gargi: A smaller reasoning model tested against Qwen
Another Udgam Labs release, Gargi, focuses on language-model reasoning. It contains 384 million parameters and was trained on approximately 17 billion tokens.
The supplied account compares Gargi with Qwen2.5-0.5B, a model described as having been trained on roughly 18 trillion tokens. Despite the substantial difference in the reported training-token counts, Gargi came within two points of the comparison model on several reasoning tests.
That result offers an interesting example of how model size and training-data volume do not, by themselves, determine performance on every benchmark. Training methods, data composition, model architecture and the nature of an evaluation can all influence the outcome.
However, Gargi’s results were not uniformly competitive. On knowledge tests, it fell well behind Qwen2.5-0.5B, according to the supplied material.
The difference between reasoning and knowledge performance is important. A model may perform relatively well on selected problems that require a particular kind of reasoning while having weaker performance on tasks that depend on broader factual knowledge.
Consequently, Gargi’s results should not be interpreted as evidence that a smaller model can generally replace a larger one. They instead suggest that targeted training can produce competitive results on some evaluations while leaving clear weaknesses elsewhere.
For researchers and developers, that distinction can help guide decisions about where compact models may be useful. A smaller system might suit a narrowly defined task if it performs reliably on the relevant tests, while a broader application could require stronger knowledge capabilities.
Five AI models, five different technical challenges
Udgam Labs’ releases span several areas of artificial intelligence rather than concentrating on a single type of model. The projects described in the supplied material cover speech recognition, reasoning, mathematics, image generation and conversational AI.
These tasks involve different technical requirements. Speech recognition converts audio into text, while conversational models generate responses to prompts. Reasoning and mathematics models are evaluated on their ability to solve structured problems, and image models address a different form of content generation.
The available source provides detailed figures for Laghu, Shruti and Gargi, but does not supply equivalent technical specifications or benchmark results for every model in the five-model group. It would therefore be premature to treat all five releases as equally evaluated or to assume that they achieved similar levels of performance.
What connects the projects is the laboratory’s focus on compact systems and public documentation. Instead of relying on the size of a model or the speed of its release as proof of success, the work invites attention to measurable performance and the conditions under which the results were obtained.
That distinction is particularly important in a field where the announcement of a new model can attract attention before its practical limitations are fully understood. Open evaluations can help separate an interesting technical experiment from a system that has demonstrated consistent performance in real-world use.
Udgam Labs publishes a benchmark for 27 small language models
Beyond its individual models, Udgam Labs has released a benchmark comparing 27 small language models, each with fewer than 400 million parameters. Prasad’s own models are included in the comparison.
The inclusion of his own systems is notable because it places them within a wider evaluation rather than presenting them only through standalone results. According to the supplied account, Udgam’s models do not always rank first.
That outcome reinforces the importance of evaluating models against alternatives. A benchmark can provide a more informative picture than a single performance claim, particularly when developers need to understand how different systems behave across the same set of tests.
For a benchmark to be useful, however, its results must be interpreted in context. The choice of tasks, test data, scoring methods and evaluation conditions affects what the rankings reveal. Performance on one benchmark cannot establish that a model is best for every application.
The reported comparison focuses on models under 400 million parameters, so its scope is specifically small language models rather than the entire AI landscape. It can help people investigate trade-offs among compact systems, but it does not by itself establish how those models compare with much larger systems across all tasks.
Publishing the benchmark alongside the laboratory’s model releases gives developers another way to examine the work. It also provides a framework for comparing results instead of judging a model solely by its parameter count, training budget or release announcement.
Why small, open AI models matter
The case for compact AI models is not simply that they are cheaper to train. Smaller models may also require less storage and computing capacity for deployment, depending on their architecture, precision, runtime and hardware environment.
Those characteristics can matter to independent developers, researchers, startups and organisations that cannot easily access large-scale infrastructure. A model designed for a specific task may be sufficient for some applications without requiring the broader capabilities of a much larger system.
Open releases can add another advantage. When developers can access model weights, code and evaluation details, they have more opportunity to inspect the system, reproduce experiments, adapt the model and assess whether it meets their requirements. The precise degree of openness depends on what is actually released and the terms under which it can be used.
Transparency also makes it easier to understand failure. If a model performs poorly on a particular language or benchmark, that weakness can inform future experiments rather than being obscured by an overall claim of success.
For Indian developers, projects that include Hindi and Hinglish speech recognition are particularly relevant to the question of how AI tools can serve multilingual users. However, the results described for Shruti apply to the specific comparison material in the source; broader claims about performance across Indian languages would require additional testing.
Compact models are not automatically more accurate, more secure or more reliable than larger alternatives. They still need suitable evaluations, careful deployment and monitoring for the tasks in which they are used. Their potential advantage lies in giving developers another set of options, with different costs and performance trade-offs.
What Prasad’s work does and does not prove
Udgam Labs’ releases provide examples of how a small laboratory can investigate AI development under resource constraints. Laghu’s reported training cost, Shruti’s small storage footprint and Gargi’s results on selected reasoning tests each highlight a different dimension of the problem.
But the evidence does not establish that compact models have made large AI laboratories unnecessary. The reported results are task-specific, and Gargi’s weaker performance on knowledge tests demonstrates that progress in one area can coexist with shortcomings in another.
Nor does a low training bill represent the full cost of building and maintaining an AI product. Development time, data preparation, evaluation, infrastructure, maintenance and deployment can all contribute to the resources required for a successful system. The supplied figures describe particular Udgam Labs projects and should not be treated as universal estimates for training AI models.
The significance of Prasad’s work lies instead in making these trade-offs visible. By releasing models, publishing evaluation material and including his own systems in a broader benchmark, Udgam Labs provides information that other developers can examine and challenge.
The results leave the central question open: can small, carefully developed models deliver enough performance for a growing range of practical tasks without the costs associated with much larger systems? The answer will depend on the application and on evidence from further evaluation.
The larger question behind Udgam Labs
Jitesh Prasad’s path from physics at the University of North Bengal to an MBA at IIM Lucknow offers context for a laboratory focused on both technical performance and the economics of development. Yet the more important measure of Udgam Labs’ work is not its founder’s background or the number of models released in a short period.
It is whether the experiments produce reproducible results that help other people build better systems. The publication of code, checkpoints, training information and evaluations gives outside developers a basis for examining that question.
Some of the reported results are promising within their stated limits; others show where smaller models still struggle. That mixture makes the work more informative than a blanket claim that compact AI has already caught up with larger systems.
Udgam Labs has put a practical question before the AI community: how much capability can be built with limited resources, and where do the compromises begin? Its five-model release sequence and benchmark provide material for investigating the question, but they do not settle it.
For now, the laboratory’s contribution is a public record of experiments that others can scrutinise, reproduce and improve. In a field often associated with vast budgets and computing infrastructure, that is a useful way to test how far a smaller approach can go.
For breaking news and live news updates, like us on Facebook or follow us on Twitter and Instagram. Read more on Latest Education on thefoxdaily.com.

COMMENTS 0